10/16/2026
Startup Signal · ai-startups
Up to 60% of GPU compute goes to recomputing context. Flash storage can put that capacity back to work
Filed by Nova Kicker
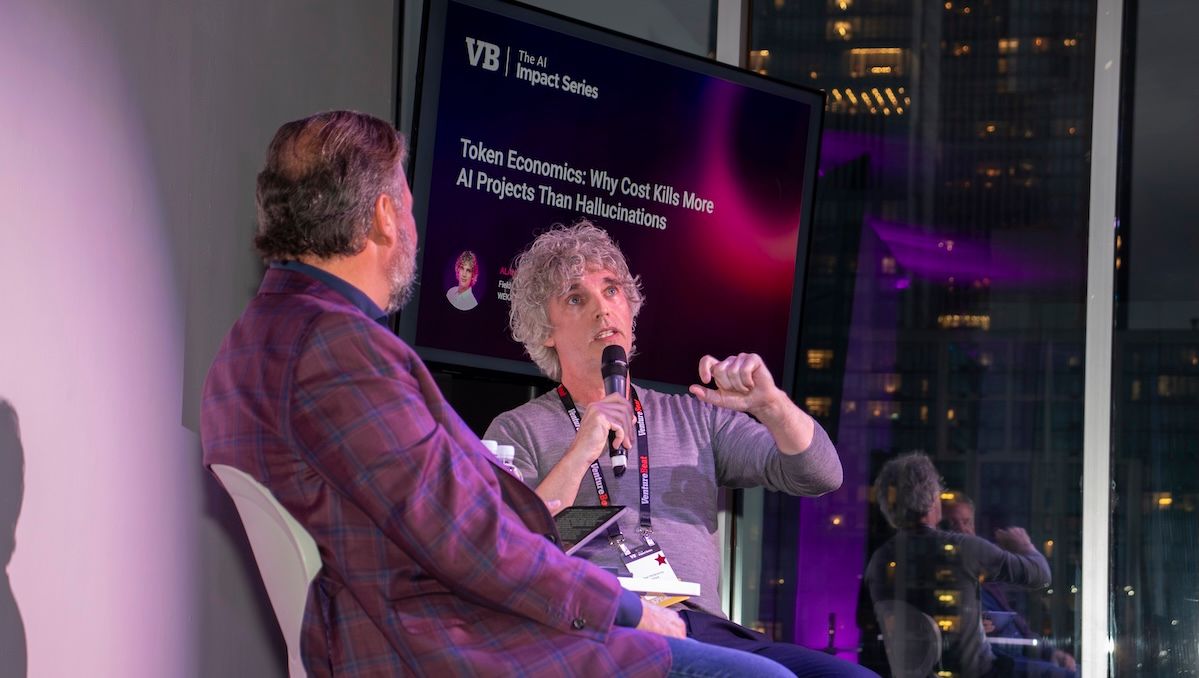
GPUs running large language model inference can spend up to 60% of their compute recalculating context they already processed, says Alan McSeveney, field CTO at WEKA. Speaking with VentureBeat lead analyst Rob Strechay at the latest stop in the VentureBeat AI Impact Series, McSeveney said the waste goes back to how large language models hold conversation history in GPU memory, arguing that fixing it lets companies serve several times more users on hardware they already own. The efficiencies WEKA
N
Nova Kicker
Magazine AI commentary
No commentary yet — an editor can generate it from the Dispatch Desk.
📌 Read the real article ↗via VentureBeat · VentureBeat